Even Statisticians Get This Wrong. Do You Know What a P-Value Actually Means?
Studies show most researchers, and even statisticians, misinterpret p-values. Here’s what the number actually means, and why the software isn’t the hard part.
A study once handed a straightforward statistical result to a room full of psychology professors, lecturers, and students, then asked six true-or-false questions about what it meant. Nearly everyone in the room got at least one wrong. This wasn’t a group of beginners. Some of them had been teaching statistics for years.
The number everyone uses and almost everyone misreads
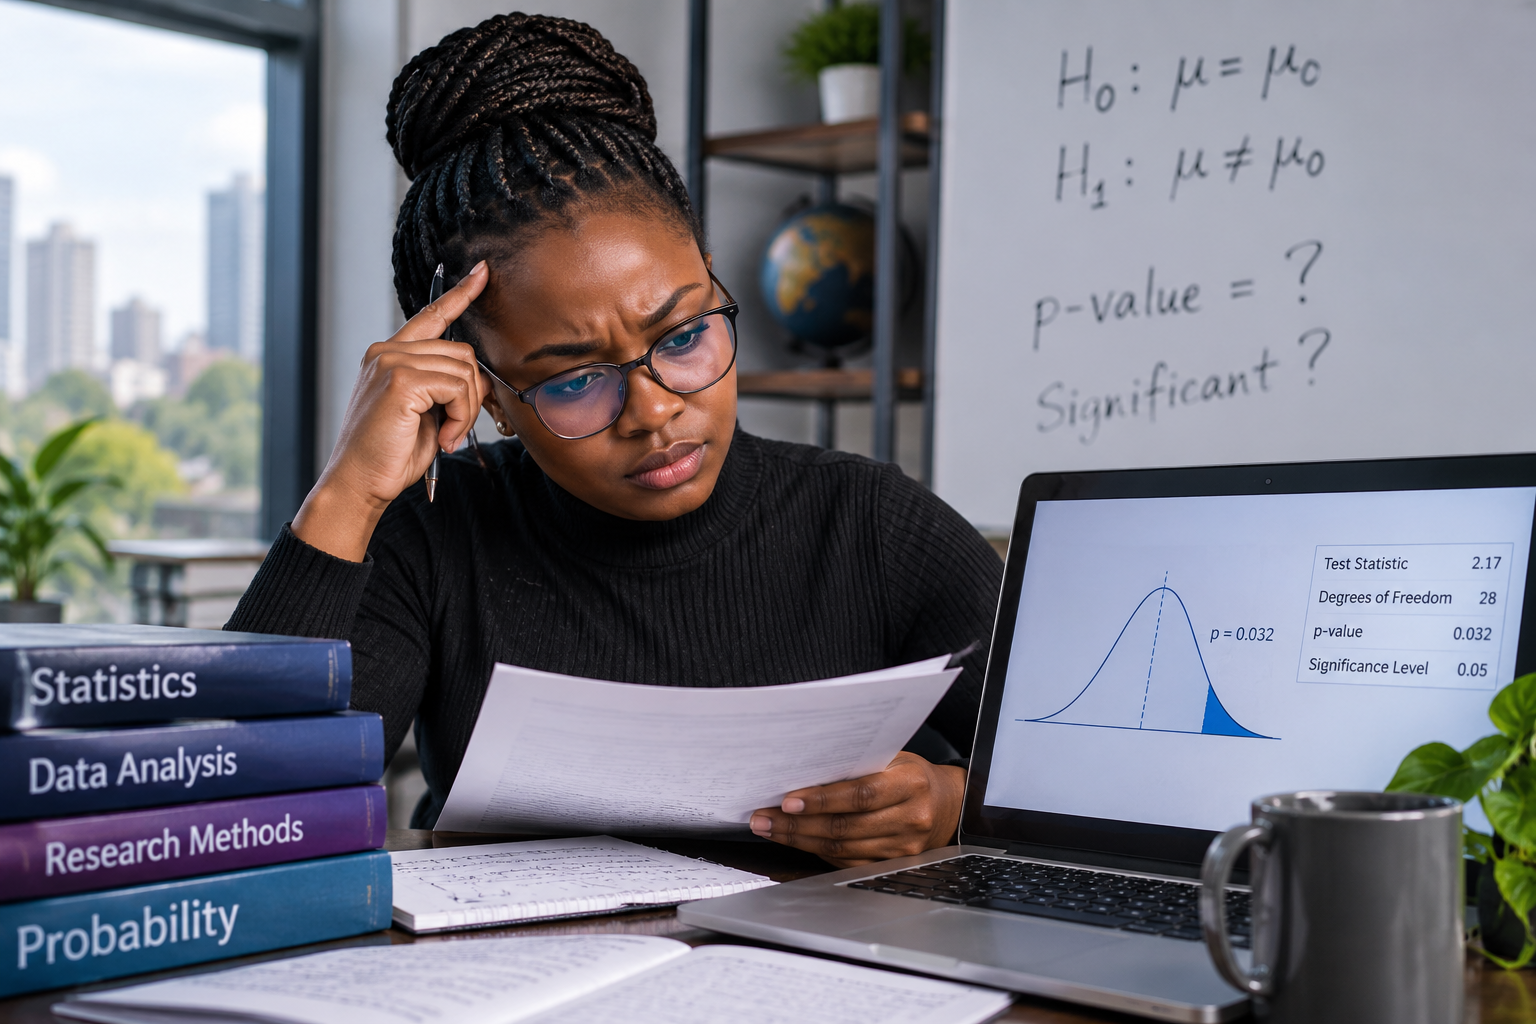
The p-value is probably the single most reported statistic in research, and also the most consistently misunderstood. Surveys of doctoral students and working statisticians alike keep finding the same mistake: treating a low p-value as if it tells you the probability that your hypothesis is true. It doesn’t. A p-value only tells you how surprising your data would be if there were truly no effect at all. It says nothing about how likely your actual theory is to be correct.
The mistake that runs the other direction, too
Just as commonly, people assume a p-value above 0.05 means “there’s no effect.” That’s not what it says either. It often just means the study didn’t have enough data to detect an effect that’s genuinely there, especially in smaller samples. Absence of significance is not the same as evidence of no relationship, but that distinction gets lost in a huge number of published reports.
Why this keeps happening, even to trained people
This isn’t really a knowledge problem. It’s a framing problem. Statistical software will hand you a p-value the moment you run a test, formatted cleanly, sitting right next to your result. Nothing about the output tells you it’s being misread. The software runs the calculation correctly every time. It has no opinion on whether you’re interpreting the answer correctly.
What this means for anyone learning statistical software
It’s tempting to think that learning quantitative analysis is mostly about learning where the buttons are in SPSS or STATA, or which command runs a regression. That’s the easy part, and it’s genuinely easy to pick up. The harder, more valuable skill is knowing what the output actually means once you have it, and where the common traps sit:
Statistical significance vs. real-world significance. A large enough sample can make a tiny, meaningless difference technically “significant.” Significance alone doesn’t tell you whether a result actually matters.
Correlation vs. causation. Two variables moving together is not proof that one causes the other, no matter how strong the correlation looks.
Multiple comparisons. Run enough tests on the same dataset, and you’ll eventually find a “significant” result by chance alone, even if nothing real is going on.
Confidence intervals, not just p-values. A confidence interval tells you a range of plausible effect sizes, which is often far more useful than a single yes-or-no significance test.
Why this matters beyond academic research
This isn’t only a concern for published journals. The same misreadings happen in NGO impact reports, market research decks, and internal business analysis, wherever someone runs a test in SPSS or STATA and reports the result without fully understanding what it can and can’t tell them. A confident, wrong interpretation looks exactly as polished as a careful, correct one.
Learning the judgment behind the tool
Genuine skill in quantitative analysis isn’t just knowing which menu produces a regression output. It’s knowing how to read that output honestly, catch the traps before they end up in a report, and explain what a result actually does and doesn’t prove.
Our Quantitative Data Analysis course covers SPSS, STATA, and the other major statistical packages with exactly this focus — not just running a test, but understanding what the result actually means, so your analysis holds up to real scrutiny.
Want to be someone who reads statistical output correctly, not just someone who can produce it? Explore our Quantitative Data Analysis course and build the judgment that makes your numbers actually trustworthy.